Morgan Washington · 12 October 2026
Data Tagging Stability in Enterprise Workflows: Integration Approaches with Plakit
Enterprise systems handle vast volumes of information daily, and data tagging stability ensures that labels remain consistent even as platforms evolve or datasets expand across departments. Plakit provides structured approaches that connect tagging processes directly to existing enterprise tools, reducing drift that often occurs during migrations or updates. Researchers at various institutions have documented how inconsistent tags lead to retrieval errors, compliance gaps, and duplicated effort, which is why stable integration methods receive ongoing attention.
Organizations typically begin by mapping current tagging schemas to Plakit’s core framework, which supports rule-based automation alongside manual overrides. This mapping phase identifies fields prone to variation, such as project codes or regulatory categories, then applies validation layers that trigger alerts when mismatches appear. Data shows that teams adopting these steps early see fewer downstream corrections because the system enforces uniformity at the point of entry rather than during later audits.
Core Components of Stable Tagging Architectures
Plakit operates through modular connectors that link to popular content management systems, databases, and collaboration platforms without requiring full platform replacements. Each connector carries predefined validation rules that check tag syntax, hierarchy depth, and cross-references against master lists maintained in a central repository. When changes occur in one system, the connectors propagate updates according to configurable policies, which prevents the fragmentation that commonly appears after software upgrades.
Version control forms another essential layer. Every tag modification receives a timestamp and author identifier, creating an auditable trail that compliance teams can query directly. In October 2026 several large-scale deployments plan to test enhanced conflict-resolution algorithms that prioritize tags based on source authority rather than simple recency, a shift expected to further reduce manual reconciliation time.
Integration Patterns Observed Across Sectors
One pattern involves embedding Plakit within existing ETL pipelines so that tagging occurs automatically as data moves between staging and production environments. This approach suits organizations that already maintain strict data lineage requirements. Another pattern places Plakit as a lightweight middleware layer that sits between user interfaces and backend storage, allowing analysts to apply tags through familiar forms while the middleware handles consistency checks in the background.
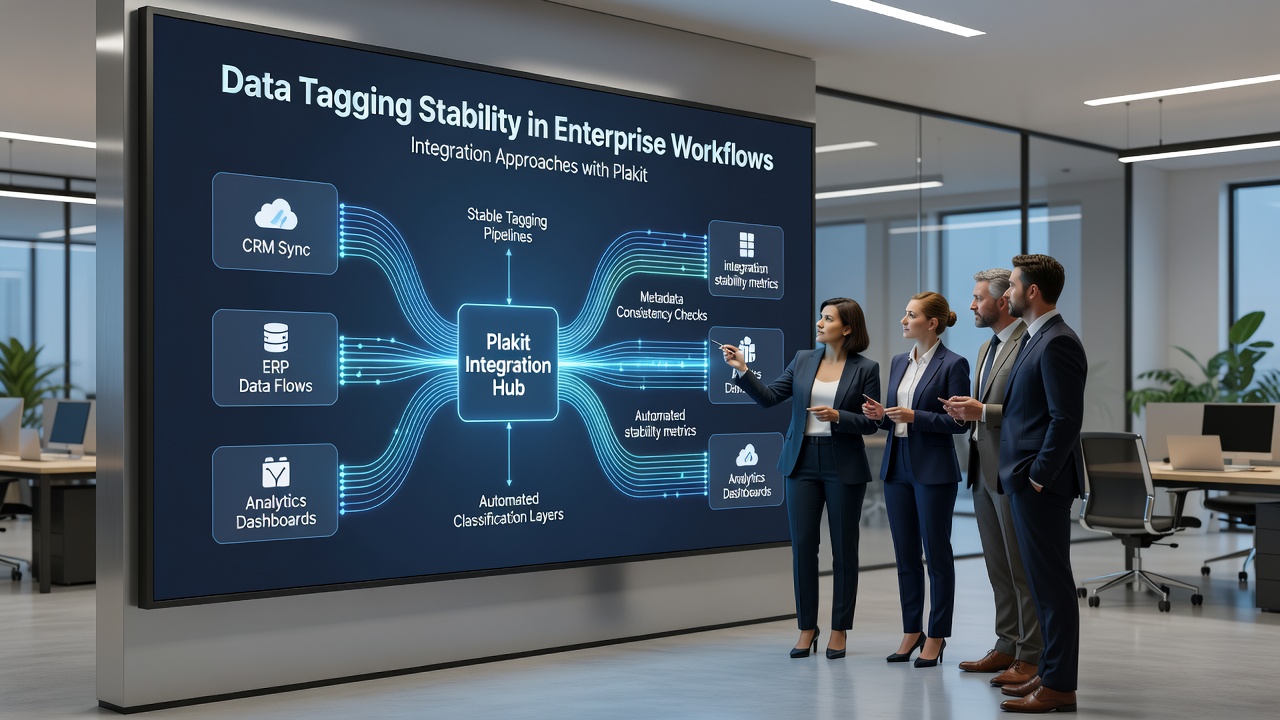
Hybrid models combine both methods, routing high-volume operational data through pipelines while routing less structured content through the middleware interface. Observers note that hybrid setups often appear in sectors handling mixed data types, such as healthcare records paired with operational logs, because the dual pathways accommodate differing validation needs without forcing a single rigid workflow.
Security and Compliance Considerations
Stable tagging directly supports regulatory obligations because accurate labels enable precise access controls and retention scheduling. According to guidance published by the National Institute of Standards and Technology, metadata integrity forms a foundational control for protecting sensitive information throughout its lifecycle. Plakit’s audit logs align with these expectations by recording not only tag values but also the context in which they were assigned or altered.
Encryption of tag repositories and role-based access to editing functions further reduce exposure risks. Teams that configure these features report fewer incidents of unauthorized label changes, which in turn supports cleaner reporting during external reviews. Research from the European Union Agency for Cybersecurity has examined similar metadata controls in multi-tenant environments, highlighting the value of centralized policy enforcement that Plakit implements through its connector architecture.
Implementation Phases and Measured Outcomes
Deployment typically unfolds across four phases: discovery, pilot testing, phased rollout, and ongoing monitoring. During discovery, analysts inventory existing tags and identify high-impact inconsistencies. Pilot testing occurs within a single department or project set, allowing teams to refine rules before wider exposure. Phased rollout expands coverage while maintaining fallback procedures that revert to previous states if anomalies surface. Monitoring continues indefinitely through dashboards that surface tag-health metrics such as duplication rates and missing-value percentages.
Figures from organizations that completed these phases indicate measurable reductions in search failure rates and manual correction hours. The improvements compound over time because stable tags improve the accuracy of downstream analytics and machine-learning models that rely on labeled training data.
Conclusion
Data tagging stability in enterprise workflows rests on deliberate integration choices that Plakit supports through connectors, validation layers, and audit mechanisms. Organizations that follow structured implementation phases consistently record fewer label inconsistencies and stronger compliance posture. As systems continue to evolve, the emphasis remains on maintaining traceable, rule-enforced tags that travel reliably across platforms and time periods.